Site Reliability Engineering · Platform Systems

Reliable systems.
Engineering with intent.

I work across Kubernetes, cloud-native platforms and critical production operations. I turn incidents into learning, tooling into platforms and architectural decisions into systems teams can operate with confidence.

Open to remote opportunities · Brazil / worldwide
mc@platform - zsh
~/systems/ evidence-first · human-in-control
Interactive local demo terminal. No commands run on a server.
01 // Caju Benefícios · historical
−67%

Lower MTTR

02 // Caju Benefícios · improvement
99.9%

Critical availability

03 // Internal platform · Caju
12

Engineering squads

04 // Scope at Caju
5

Amazon EKS clusters

01 / ABOUT

Behind reliable systems are decisions that hold up under pressure.

I make complex operational problems easier to understand, prevent and resolve.

I started with Linux infrastructure and systems that could not stop. Today I work across architecture, reliability and developer experience, combining deep technical execution with engineering leadership.

At Caju Benefícios, my scope covered five EKS clusters, approximately 60 microservices and 12 squads. SLOs, incident response, observability and automation became tools for day-to-day engineering decisions.

At Ambev / AB InBev, I worked on internal platforms and self-service developer experiences, including a service catalog and reusable workflows.

LinuxKubernetesAWS / EKSAzure / AKSTerraformArgo CDOpenTelemetryPythonBackstageSLO / SLIIncident response
02 / EXPERIENCE

Where the decisions were tested.

Hands-on engineering, reliability and platforms at scale.

Oct 2023 - Jan 2026
Caju Benefícios

SRE Tech Lead · DevOps & Platform Engineering

Reliability, GitOps, observability and internal platform work across 12 squads in a regulated fintech environment.

  • MTTR from ~120 to ~40 minutes; time to detect from ~30 to ~2 minutes.
  • Critical-service availability from 99.5% to 99.9%; ~40% fewer recurring incidents.
  • New environment provisioning from ~5 working days to less than a day via self-service and IaC.
Jan 2020 - Aug 2023
Ambev / AB InBev

Principal SRE · Platform Engineering

Internal platform development and distributed systems, working with Azure/AKS, Kubernetes, CI/CD and developer experience.

  • Backstage catalog of 800+ services, improving discoverability for engineering teams.
  • Golden Paths, automation and standardized delivery workflows for product engineering teams.
Jan 2013 - Dec 2019
Endurance International Group / HostGator

Senior DevOps & Infrastructure Engineer

Linux infrastructure and automation supporting high-volume, always-on operations.

  • Infrastructure modernization and provisioning automation using Linux, AWS, Jenkins, Terraform, Ansible and Python.
03 / PROJECTS

Code, architecture and outcomes.

Projects and case studies with explicit trade-offs, limitations and inspectable evidence.

OPEN SOURCE / INCIDENT INVESTIGATION

AI-SRE-RCA

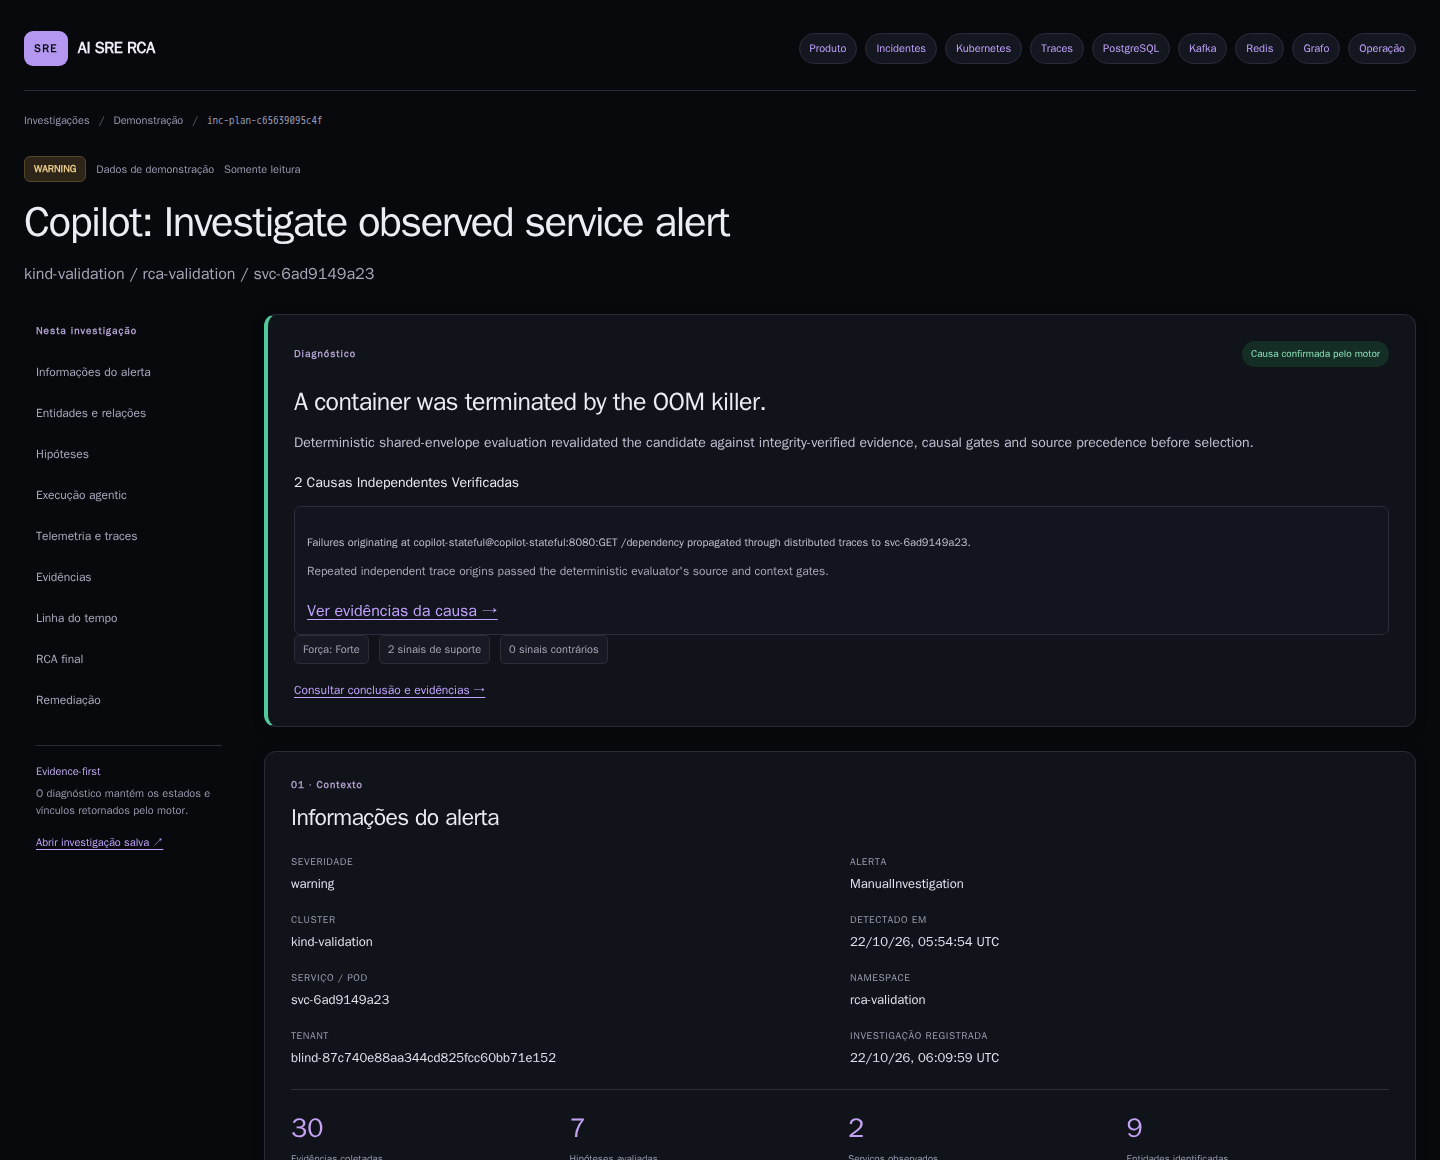
Evidence-first investigations for Kubernetes and distributed services. Read-only data collection, deterministic evaluation and optional AI assistance without delegating root-cause decisions to a model.

FastAPINext.jsKubernetesRCAOpenTelemetry
Read case study
AI-SRE-RCA running locally with controlled Kind telemetry and evidence linksActual local demo screenshot, not production
CASE / PRODUCTION

Reliability at Caju

SLOs, incident response, GitOps and observability with historical, measurable outcomes: lower MTTR, faster detection and fewer recurring incidents.

SLOsEKSGitOps
Where the decisions were tested. ↗
MTTR ~120m~40m ↓67%HISTORICAL IMPACT / CAJU
CASE / PLATFORM

Developer Platform

Backstage, self-service capabilities and standardized delivery paths to reduce friction for engineering teams.

BackstageTerraformSelf-service
Where the decisions were tested. ↗
CatalogBackstageGolden PathSelf-serviceDeliveryGitOpsCONCEPTUAL PLATFORM FLOW
04 / ARCHITECTURE

An investigation you can trace, from signal to decision.

An interactive reference architecture inspired by AI-SRE-RCA. Not connected to live infrastructure.

CONCEPTUAL DIAGRAM · SELECT A COMPONENTINTERACTIVE MODEL · NO LIVE TELEMETRY
SELECTED LAYER

Evidence collection

Metrics, logs, traces and Kubernetes events are queried within authorized scope.

Conceptual view · not a production availability display

↗ Read case study
05 / WRITING

Notes from operating real systems.

Practical engineering notes. Editorial drafts prepared for review before publishing.

MC / ENGINEERING JOURNAL

Published articles

Articles will appear here after publishing in the CMS.

Browse articles ↗

06 / CONTACT

Let’s work on problems that matter.

Happy to discuss Senior, Specialist, Staff and Principal opportunities in SRE, Cloud and Platform Engineering. Remote in Brazil or internationally.